Private AI: The Case for Keeping Your Data Off Someone Else's Servers
Think about the last few things you pasted into a chatbot: a draft email to a client, a spreadsheet with names and numbers, a contract clause, an error log with hostnames, a test result, an idea you haven’t told anyone. Every one copied itself, travelled across the internet, and landed on a machine owned by somebody else — where it now sits under policies you never read, can’t negotiate, and can’t revoke.
We got here because cloud AI is genuinely good and genuinely easy. But “easy” and “safe” are different words. This is the honest ledger: what happens to your data at the inference providers, and what changes when the model runs on hardware you own — private AI.
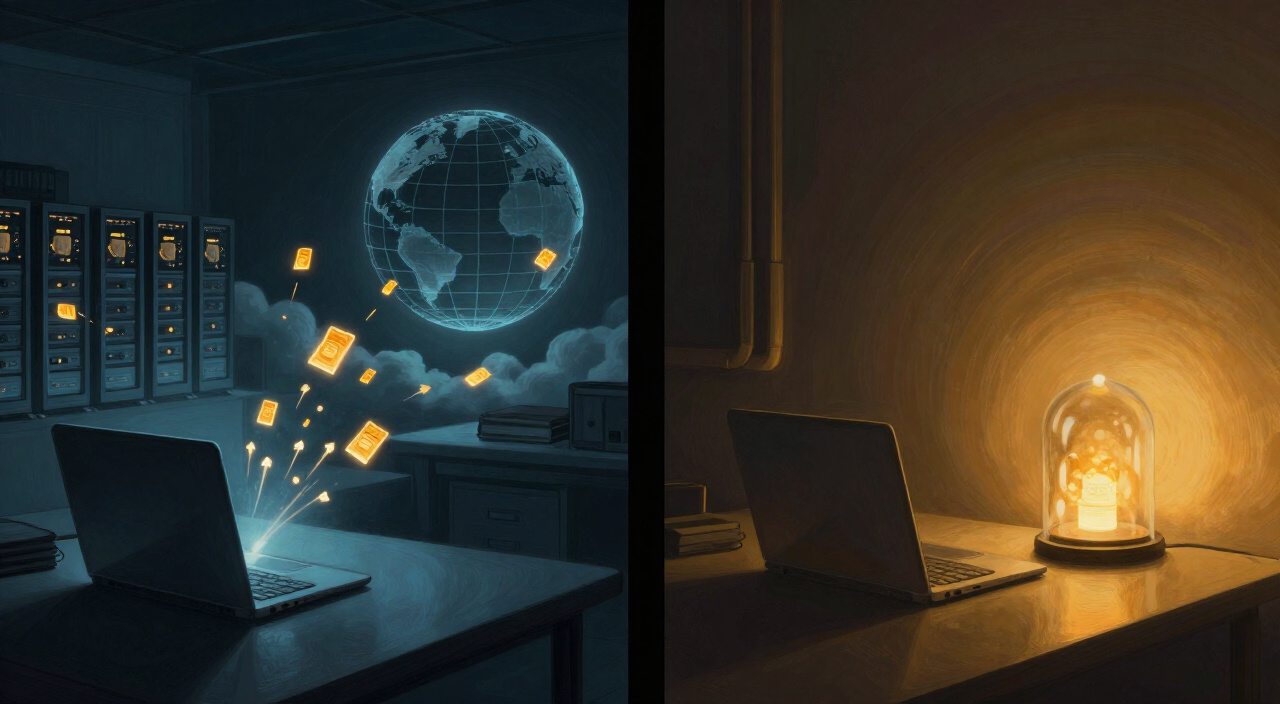
What actually happens to your prompt
The moment you hit send, your prompt stops being solely yours: load balancers, inference nodes, request logs, backups. Copies are the business model, and each copy is a place your data now lives.
- Retention. Providers keep prompt and response text for weeks at minimum, sometimes indefinitely for “abuse monitoring.” Consumer terms have historically defaulted retention on, with the opt-out buried in settings and prospective only. What you pasted last month is still wherever it went.
- Training. Terms have repeatedly moved the goalposts: from “we don’t train on your data” to “we may, unless you opt out,” with training rights baked into free tiers. Even with opt-outs honored, the burden of proof sits entirely on their side of the API.
- Humans and subprocessors. Third-party reviewers see real prompts, and your data answers to the legal process of whatever country the servers sit in. That’s why “data stays in-region” is a compliance checkbox: the concern isn’t hackers, it’s subpoenas.
None of this requires the provider to be evil — it’s the disclosed, legal, normal operation of the service. The point is that you’ve outsourced the confidentiality of your most sensitive material to a party whose incentives are storage and analysis, and you can’t audit them.
It’s not just privacy — it’s fragility
Even if you don’t care about privacy, cloud inference is a system you don’t control: the model swaps under you, prices and rate limits change on someone else’s quarterly interest, their outage becomes yours, and products get deprecated, shut down, re-priced. If your workflow is built on their API, your workflow is on their roadmap.
What private AI actually means
Not a product category — an architectural choice: the weights run on hardware you own and the data path never leaves it. Open-weight models (Llama, Qwen, Mistral) are now good enough that a 20–30-billion-parameter model on one workstation covers the everyday work people use cloud chatbots for. The stack is boring in the best way: a GPU box, a server like Ollama or vLLM, a chat UI, and a local embedding model that indexes your documents where they never left. I built exactly that setup, quirks and all (my field notes here).
What you get back
- Sovereignty. The most important property is the quietest: nothing happens. No copy lands anywhere, no retention clock starts, and no policy change six months from now can retroactively expose last year’s material because there is nothing out there to expose. Privacy stops being a promise and becomes a physical fact you can point at.
- Cost that stops being a meter. Cloud inference is a utility bill, metered forever; local is a capital purchase — hardware once, cents of electricity per query. For daily heavy use the crossover comes early, with no rate-limit anxiety.
- Availability. It works through internet outages and provider incidents, identically at 2 a.m. The weights don’t change unless you change them.
- Compliance without gymnastics. For regulated material — client records, health data, government data-residency — “the data never leaves the building” is the shortest possible answer to every due-diligence questionnaire.
The honest trade-offs
You pay in patience: first tokens in seconds, not milliseconds, and frontier cloud models are faster and at the very top end still smarter. There is a capability ceiling — but local models already cover the 90% of work that involves your data, and the ceiling tasks rarely involve sensitive data anyway. And you own the ops: if it breaks at midnight, the status page is you. The counterpoint is that a machine running the same software forever is far more predictable than a service shipping changes under you.
My actual posture is a split: anything about me, my family, my clients, or my employer goes to the local model, full stop; public, generic questions can use a hosted API when I want the extra horsepower. That’s not paranoia — it’s data classification with a router made of common sense.
The takeaway
Cloud AI made intelligence convenient, and it will keep getting better. But convenience bought with copies of your life is a specific kind of debt — invisible, deferred, priced by someone else. Running the model yourself costs hardware and patience, and buys the one thing you can’t get back once it’s gone: the certainty that when you typed it, it stayed here.
— Kris